
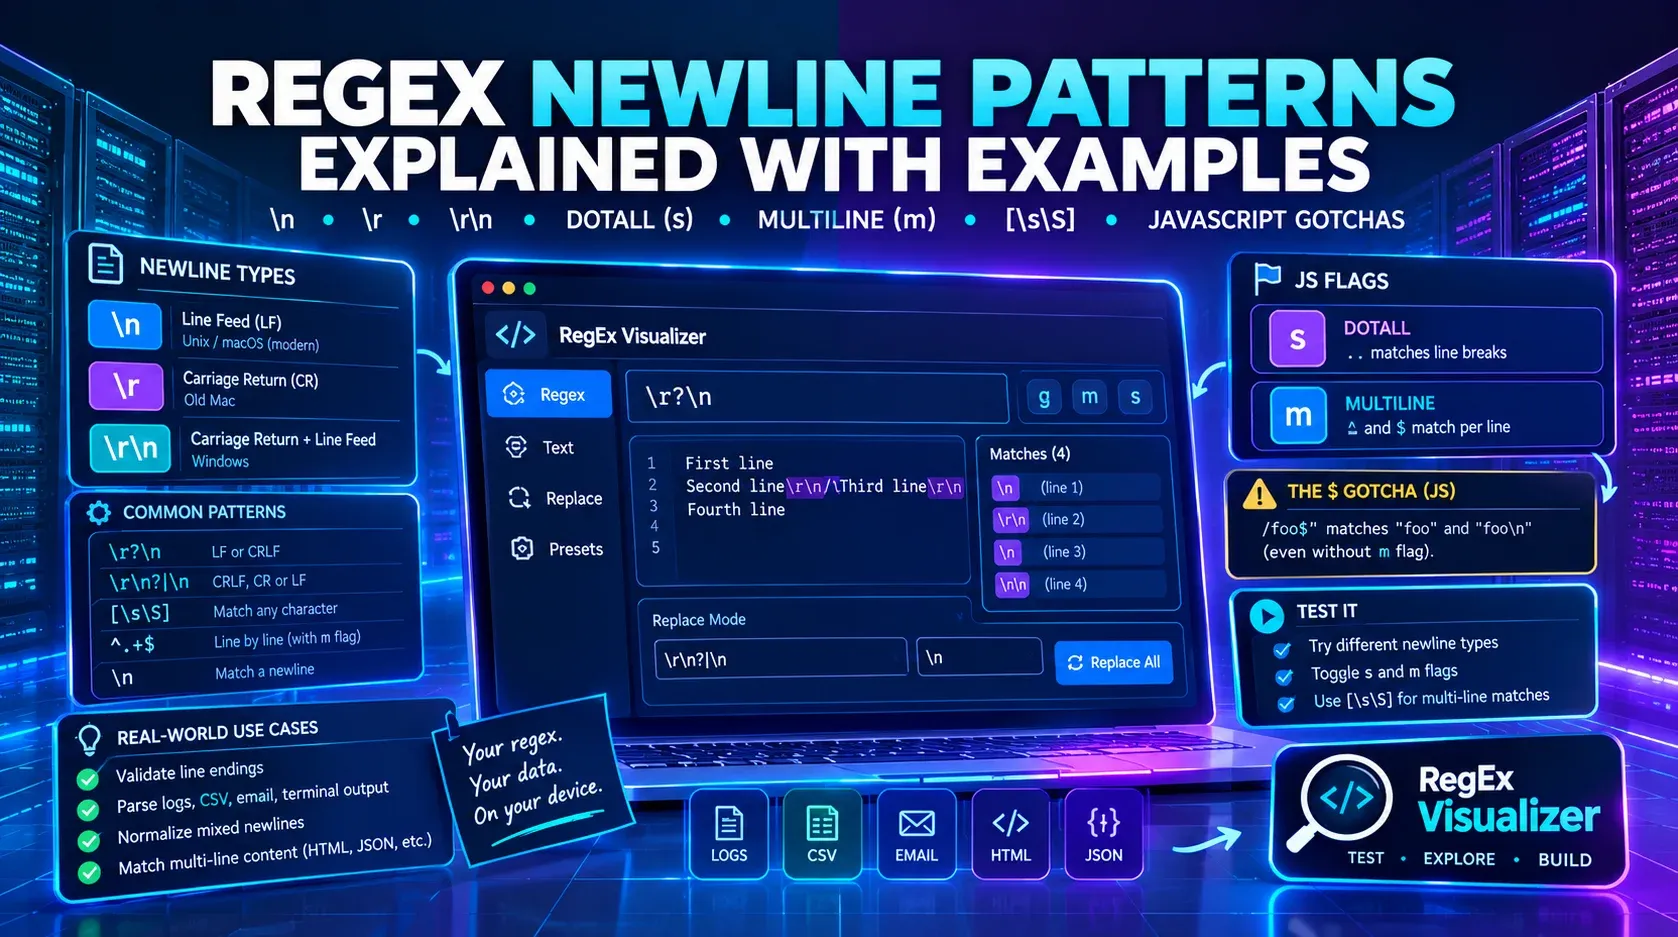
How to Match a Newline in Regex: Quick Answer
A regex newline pattern matches line breaks inside a string or file. The tricky part is that a line break isn't always one character. Unix and modern macOS text usually use \n, classic Mac text used \r, and Windows text commonly uses \r\n. A pattern that works on one pasted sample can fail on logs, CSV files, email text or copied terminal output if it assumes the wrong newline style.
This guide covers \n, \r, \r\n, the dotAll (s) and multiline (m) flags, the portable [\s\S] trick for matching across lines, and how the $ anchor treats a trailing newline in JavaScript versus other engines. You can test every example in RegEx Visualizer, a browser regex tester from ToolsViewer that matches with JavaScript RegExp and includes Replace mode and presets. Your pattern and sample text stay on your device.
To match a line break in JavaScript and most common regex engines, start with \r?\n. It matches a Unix line feed and a Windows carriage-return-plus-line-feed pair. If you also need to accept isolated carriage returns, use \r\n?|\n. If your engine supports \R, as PCRE2 does, that matches a broader set of newline sequences, but \R is not a JavaScript feature.
Regex Newline Cheat Sheet
\nmeans line feed (LF).\rmeans carriage return (CR).\r\nmeans CRLF, common in Windows files and many network formats.\r?\nmeans an optional CR followed by LF, so it matches both LF and CRLF.\r\n?|\nmatches CRLF, a lone CR, or LF.[^\r\n]+matches one or more characters that are not line breaks.[\s\S]matches any character, including newlines.
The right choice depends on where the text comes from. Browser textareas often normalize line endings before your JavaScript sees them. Files, copied log excerpts and email sources may preserve mixed endings. When you're unsure, paste real examples into the tester and check the visible matches instead of guessing from the operating system.
Regex $ and the Trailing Newline: JavaScript vs Other Engines
This is one of the most misunderstood parts of regex, because engines disagree.
In JavaScript, $ without the m flag matches only at the very end of the input. A trailing newline is just another character, so it is not ignored. That means /foo$/ matches "foo" but does not match "foo\n".
In Python, Perl and PCRE, the default $ is more forgiving. It matches at the end of the string and also just before a final newline. So the same pattern can match "foo\n" there. If you move a regex between languages, this difference can quietly change validation results.
How to test it yourself in JavaScript
- Open RegEx Visualizer.
- Enter the pattern
foo$with no flags set. - Test it against "foo". It matches.
- Test it against "foo\n". It does not match, because the string no longer ends right after foo.
- Test it against "foo\nbar". It does not match either.
- Now add the m flag and test "foo\nbar" again. With m, $ matches at the end of every line, so foo now matches.
How to allow an optional trailing newline
If your input may end with a line break and you still want an "ends with" check, say so explicitly:
foo\r?\n?$This matches foo, foo\n and foo\r\n. Being explicit is safer than relying on engine-specific $ behavior. This matters most when you validate line endings, check whether a string ends with something, or write a pattern meant to reject trailing whitespace or blank lines.
Why the Dot Does Not Match a Newline
In most regex engines, the dot (.) means any character except a line terminator. That is why a pattern like <.*> may work for one-line HTML but fail as soon as the opening and closing tags are separated by line breaks. The dot isn't broken. It is following the default rule.
To match any character including newlines, choose one of these approaches:
- Enable the s flag (dotAll) so . can match line breaks.
- Use
[\s\S], a character class meaning whitespace or non-whitespace, which covers every character. - In some flavors, use an engine-specific mode or token, but confirm your production engine supports it before relying on it.
Example: match a multi-line HTML comment
<!--[\s\S]*?-->This finds an HTML comment that spans several lines. The *? quantifier is non-greedy (lazy), so it stops at the next closing marker instead of racing to the last one in the string. In RegEx Visualizer, add two comments to your sample text and confirm the pattern returns two matches, not one giant match.
DotAll (s) Flag vs Multiline (m) Flag
The s and m flags solve two different newline problems, and confusing them is one of the most common regex mistakes.
- The s flag changes dot behavior: . can now match line breaks.
- The m flag changes anchor behavior:
^and$can match the start and end of each line, not only the start and end of the whole string.
For example, ^ERROR with the m and g flags finds every line that begins with "ERROR". Without m, it only matches if the entire string begins with that word. By contrast, ERROR.*END needs the s flag if "ERROR" and "END" may appear on different lines. Many real-world patterns use both flags together: m to locate line boundaries, and s to let a section's body span multiple lines.
Using Anchors for Line-by-Line Matching
Newline questions often come down to anchors. Use ^.+$ with the m flag to match non-empty lines, or ^\s*$ with m to find blank or whitespace-only lines. Remember that \s includes newlines, so be careful when a line pattern contains \s*. If that token can consume the line break itself, the match may stretch farther than expected.
When the goal is to capture whole lines, prefer patterns that explicitly exclude line breaks, such as [^\r\n]+. That character class means "one or more characters that are not a carriage return and not a line feed." It is often clearer than relying on dot behavior, especially when a teammate might later toggle the s flag and unintentionally change matching elsewhere in the pattern.
Split, Replace and Normalize Newlines
Replace mode is the easiest way to see exactly what a newline regex will do before you run it on real data.
- Normalize mixed line endings to LF: match
\r\n?|\nand replace with the newline character your target language expects. - Remove blank lines: start with
^\s*\r?\nusing the g and m flags, then test against lines that contain only spaces or tabs to confirm they are caught too. - Join wrapped lines without destroying paragraph breaks: don't blindly replace every
\r?\nwith a space. First decide what counts as a paragraph boundary. A common approach replaces single line breaks with a space but leaves two or more line breaks intact. A starting pattern for double breaks is(?:\r?\n){2,}, but real text often includes blank lines that contain trailing spaces, so you may need(?:\r?\n[ \t]*){2,}instead.
JavaScript Flags and Export Quoting
RegEx Visualizer matches using JavaScript's RegExp engine. Modern browsers support the s and m flags for every example on this page. Tokens such as \R are a PCRE concept and are not available in JavaScript, so stick to \r?\n or \r\n?|\n when you need portable newline matching in the tool.
The tester shows match behavior, but host language syntax still matters. In JavaScript source code, a regex literal like /\r?\n/g isn't written the same way as a string passed to new RegExp(). Export snippets for other languages are copy-paste helpers for quoting and API shape, not alternate match engines. Confirm the pattern's behavior in the visualizer first, then adapt the string quoting for your target codebase.
Whitespace Overlap: \s vs Newlines
\s already includes newline characters. That is useful for matching any kind of spacing but risky when you only meant a literal space. If you're cleaning text and want spaces or tabs without crossing lines, use [ \t] instead of \s.
The opposite also matters. \S+ stops at newlines, because newlines count as whitespace. That makes \S+ useful for matching tokens or words, but not whole paragraphs. Use [\s\S]+? or the dotAll flag when a match needs to cross line boundaries. For a deeper breakdown of whitespace matching in general, see our guide on regex space and whitespace.
Try It Step by Step
- Open RegEx Visualizer.
- Paste a multi-line sample with a blank line, an indented line and text that should not be matched.
- Try
\n, then\r?\n, then\r\n?|\n. - Toggle the m flag and test ^ and $ line anchors across multiple lines.
- Toggle the s flag and compare . against
[\s\S]. - Test foo$ with no flags against "foo", "foo\n" and "foo\nbar" to see exactly where JavaScript's $ matches.
- Open Replace mode to preview newline normalization before changing real text.
FAQ
How do I match a newline in regex?
\n for a line feed, or \r?\n to cover both Unix (LF) and Windows (CRLF) line endings. Test live in RegEx Visualizer.What is the difference between \n and \r\n?
\n is a single line feed, used on Unix, Linux and modern macOS. \r\n is a carriage return followed by a line feed, used on Windows and in many network protocols.Why doesn't the dot match a newline?
. matches any character except line terminators. Enable the s (dotAll) flag, or use [\s\S], to match across lines.What is the difference between the s and m flags?
s flag lets . match newlines. The m flag makes ^ and $ match at the start and end of each line.Does $ match before a trailing newline in JavaScript?
m flag, JavaScript's $ matches only at the very end of the string. Python, Perl and PCRE behave differently, so test when you port a pattern.Is \R supported in JavaScript?
\R is a PCRE feature. In JavaScript, use \r?\n or \r\n?|\n.How do I match across multiple lines?
s flag with .*?, or use [\s\S]*?. Both let the match cross line breaks.Conclusion
Matching newlines in regex comes down to knowing your line endings and your flags. Use \r?\n as a safe default, [^\r\n]+ to capture whole lines, m for line-by-line anchors and s or [\s\S] to match across lines. Don't rely on engine-specific $ behavior around trailing newlines. Be explicit instead, and test with real samples that include LF, CRLF and blank lines.
Test your patterns live in RegEx Visualizer, and use Replace mode to preview changes before touching real data.